Skip to Main Content

BENCHMARKS · RTX 5080 · DGX SPARK · RTX 3060

Every Second, Accounted For.

Real runs of MiniMax H3 and Qwen-Image 2.1 on the author’s two machines and three GPUs: an RTX 5080 and an RTX 3060 in one PC, plus a DGX Spark. Every step names the device it ran on. Use the tables to pick a setup for your own hardware. Failures are listed as failures.

  • First-frame video, fl2va

    57.2–76.0 s

    5.17 s, 768×448, 124 frames, with sound

    4 runs on 2026-10-18 · end to end

    76 s is the first fl2va run on 2026-10-18: first-frame encode 6.1 s and audio decode 5.8 s, about 1 s in the three after it; its DiT and video decode were slower too.

    • DGX Spark (GB10)
    • RTX 5080
    • RTX 3060
    • PC CPU
  • Reference video, ref2va

    105.0–108.0 s

    One reference image, same output

    2 runs on 2026-10-18 · end to end

    • DGX Spark (GB10)
    • RTX 5080
    • RTX 3060
    • PC CPU
  • Qwen-Image 2.1 still

    25.8–26.9 s

    1152×672, 40 steps

    4 runs on 2026-10-18 · end to end

    • RTX 5080
    • PC CPU

One Render, Three GPUs

ref2va · run 5adf4237 · Measured 2026-10-18

  1. 1

    Text encode

    • te-gb108.3 s
  2. 2

    Reference / first-frame encode

    • venc-50805.5 s
    • aenc-30601.5 s
  3. 3

    DiT denoise

    • dit5080-ref2va-fp8-pai868.0 s
  4. 4

    Video and audio decode

    • vae-508022.5 s
    • audio-30600.9 s
  5. 5

    Mux

    • mux0.3 s
  • RTX 508016 GB (recorder card total 15.92 GiB)
  • DGX Spark (GB10)128 GB unified memory, shared by CPU and GPU
  • RTX 306012 GB
  • PC CPU62.6 GiB RAM (also holds the pinned weights that stream to the RTX 5080)

Early runs on 2026-10-17 encoded references on the RTX 3060; they moved to the RTX 5080, about 3.4× faster.

  • fl2va · Text encode · te-gb101.4 s
  • fl2va · First-frame encode · venc-50801.0 s
  • fl2va · DiT · dit-508031.7 s
  • fl2va · Video decode · vae-508022.8 s
  • fl2va · Audio decode · audio-30600.9 s
  • fl2va · Mux · mux0.3 s
  • ref2va · Text encode (with reference) · te-gb108.3 s
  • ref2va · DiT (one reference image) · dit5080-ref2va-fp8-pai868.0 s
  • t2i · Qwen-Image DiT · qimg-dit-bf16-5080-stream≈23.5 s

Six Things to Know

Read these first, then find your setup in the speed table.

  1. 6.0–6.4×

    Original 50-step ÷ PAI 8

    Schedule Beats Precision

    PAI 8 (an 8-step schedule) is 6.0–6.4× faster than the original 50 steps. At the same schedule, INT8 is only 3.6–10.2% faster than FP8 (denoise compute; single cold runs with one seed, so treat small gaps as indicative).

    See the Data
  2. 600.5 → 297.2 s

    One segment, end to end

    References Are the Cost — 448 Halves It

    In a character-swap run the reference video is 47% of the DiT sequence. Preprocessing it at a 448-pixel short edge (instead of 768) cut one segment from 600.5 s to 297.2 s.

    See the Data
  3. 15.91 / 15.92 GiB

    Whole-card NVML peak

    16 GB Fits, Barely

    With references the DiT reserves up to 13.6 GiB and the whole card peaks at 15.91 of 15.92 GiB. Headroom of 1.6 GiB held; 0.8 GiB did not.

    See the Data
  4. 3.4×

    Reference video encode, RTX 5080 vs. RTX 3060

    Put Each Encoder Where It Fits

    The full-precision Qwen3-VL text encoder (te-gb10) stays on the DGX Spark: about 52 GB resident, up to 60 GB during a call — far more than a 16 GB card can spare next to the DiT. Reference video encoding moved from the RTX 3060 to the RTX 5080: 72–74 s instead of 248–250 s.

    See the Data
  5. 4 / 4

    Seeds that leaked

    Turbo 4 Is Fast, but It Leaks

    In character-swap runs (768 reference video, two characters), Turbo 4’s DiT takes 229–236 s versus 466–473 s for PAI 8 — yet the source character’s costume leaked into the output on 4 of 4 seeds. Production ref2va stays on PAI 8.

    See the Data
  6. 16

    Runs that failed or were canceled

    What Failed, and Why

    Three NF4 DiTs failed to load, Turbo 4 was rejected when the pipeline forced 8 steps, three characters at 768 ran out of GPU memory, and the BF16 phase image DiT was refused before it started (not enough free VRAM). All of it is in the table.

    See the Data

The Speed Table

Each row is one real run: pipeline, DiT variant, output, every step’s time and device, DiT time, end-to-end total and VRAM. Featured rows come first; load all rows to sort and filter everything.

32 featured rows of 77 ·

The Speed Table
RunPipeline and InputsDiT VariantSteps and Devicess?wall / Computes?GiB?allocated / reservedcardStatus
fl2va

First frame: a Qwen-Image still from the same day

FP8 · PAI 8768×448 · 124 fdit-5080
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
38.776.0Not reportedOK
fl2va

First frame: a Qwen-Image still from the same day

FP8 · PAI 8768×448 · 124 fdit-5080
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
32.057.2Not reportedOK
fl2va

First frame: a Qwen-Image still from the same day

FP8 · PAI 8768×448 · 124 fdit-5080
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
31.757.4Not reportedOK
fl2va

First frame: a Qwen-Image still from the same day

FP8 · PAI 8768×448 · 124 fdit-5080
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
33.258.6Not reportedOK
ref2va

1 reference image: a character sheet from the same day

FP8 · PAI 8768×448 · 124 fdit5080-ref2va-fp8-pai8
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
70.0108.0Not reportedOK
ref2va

1 reference image: a character sheet from the same day

FP8 · PAI 8768×448 · 124 fdit5080-ref2va-fp8-pai8
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
68.0105.0Not reportedOK
t2va

Text prompt only

FP8 · PAI 8768×448 · 124 fdit-5080
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
37.8Compute28.9Not end to endrun 64.0 s3.66 / 4.93card 7.22OK
t2va

Text prompt only

INT8 · PAI 8768×448 · 124 fdit5080-fl2va-int8-pai8
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
33.2Compute26.0Not end to endrun 60.2 s3.65 / 4.93card 7.22OK
t2va

Text prompt only

BF16 · PAI 8768×448 · 124 fdit5080-fl2va-bf16-pai8
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
65.2Compute58.5Not end to endrun 91.7 s4.67 / 6.37card 8.66OK
t2va

Text prompt only

FP8 · Turbo 4768×448 · 124 fdit5080-fl2va-fp8-lx4
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
44.6Compute33.5Not end to endrun 73.4 s6.18 / 7.32card 9.63OK
t2va

Text prompt only

INT8 · Turbo 4768×448 · 124 fdit5080-fl2va-int8-lx4
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
40.6Compute31.5Not end to endrun 67.8 s6.17 / 7.31card 9.61OK
t2va

Text prompt only

FP8 · Turbo 8768×448 · 124 fdit5080-fl2va-fp8-lx8
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
57.8Compute48.4Not end to endrun 85.0 s6.18 / 7.32card 9.63OK
t2va

Text prompt only

INT8 · Original 50-step768×448 · 124 fdit5080-fl2va-int8-base
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
174.5Compute166.6Not end to endrun 201.7 s4.88 / 5.96card 8.27OK
t2va

Text prompt only

BF16 · Original 50-step768×448 · 124 fdit5080-fl2va-bf16-base-exactOfficial precision
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
413.5Compute407.8Not end to endrun 440.1 s6.31 / 8.93card 11.24OK
ref2va

2 character reference images (transparent PNG)

FP8 · PAI 8768×448 · 124 fdit5080-ref2va-fp8-pai8
DGX Spark (GB10)RTX 3060RTX 5080PC CPU
120.9Compute115.5Not end to endrun 144.2 s6.43 / 10.13card 12.42OK
ref2va

2 character reference images (transparent PNG)

INT8 · PAI 8768×448 · 124 fdit5080-ref2va-int8-pai8
DGX Spark (GB10)RTX 3060RTX 5080PC CPU
119.4Compute110.3Not end to endrun 146.7 s6.43 / 10.09card 12.37OK
ref2va

2 character reference images (transparent PNG)

FP8 · Turbo 4768×448 · 124 fdit5080-ref2va-fp8-lx4
DGX Spark (GB10)RTX 3060RTX 5080PC CPU
91.1Compute78.6Not end to endrun 118.2 s8.52 / 12.27card 14.58OK
ref2va

2 character reference images (transparent PNG)

INT8 · Turbo 4768×448 · 124 fdit5080-ref2va-int8-lx4
DGX Spark (GB10)RTX 3060RTX 5080PC CPU
83.9Compute74.4Not end to endrun 111.6 s8.51 / 12.22card 14.53OK
ref2va

2 character reference images (transparent PNG)

NF4 · Turbo 4768×448 · 124 fdit5080-ref2va-nf4-lx4AdaLN off
RTX 5080
——Not measuredFailed to load
ref2va

2 character reference images (transparent PNG)

INT8 · Turbo 8768×448 · 124 fdit5080-ref2va-int8-lx8
DGX Spark (GB10)RTX 3060RTX 5080PC CPU
140.7Compute130.0Not end to endrun 167.6 s8.51 / 12.22card 14.53OK
ref2va

2 character reference images (transparent PNG)

INT8 · Original 50-step768×448 · 124 fdit5080-ref2va-int8-base
DGX Spark (GB10)RTX 3060RTX 5080PC CPU
682.9Compute672.3Not end to endrun 709.9 s7.22 / 10.86card 13.16OK
ref2va

2 character reference images (transparent PNG)

BF16 · Original 50-step768×448 · 124 fdit5080-ref2va-bf16-base-exactOfficial precision
DGX Spark (GB10)RTX 3060RTX 5080PC CPU
1,515.5Compute1,507.3Not end to endrun 1,543.0 s8.37 / 13.06card 15.37OK
ref2va

2 character images + 5.17 s reference clip with audio

FP8 · PAI 8768×448 · 124 fdit5080-ref2va-fp8-pai8
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
470.7Compute464.3600.511.15 / 12.54card 15.70OK
ref2va

2 character images + 5.17 s reference clip with audio

INT8 · Turbo 4768×448 · 124 fdit5080-ref2va-int8-lx4
DGX Spark (GB10)RTX 3060RTX 5080
——11.60 / 13.61card 14.86Out of GPU memory
ref2va

Reuses R5’s conditioning

INT8 · Turbo 4768×448 · 124 fdit5080-ref2va-int8-lx4-fixedAdaLN fixed
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
229.3Compute227.1Not end to endrun 256.8 s11.37 / 12.76card 15.91OK
ref2va

2 character images + 5.88 s clip

FP8 · PAI 8768×448 · 141 fdit5080-ref2va-fp8-pai8
DGX Spark (GB10)RTX 5080RTX 3060
——11.83 / 12.58card 15.54Out of GPU memory
ref2va

2 character images + 5.88 s clip

INT8 · Turbo 4768×448 · 141 fdit5080-ref2va-int8-lx4-fixedAdaLN fixed
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
269.9Compute266.5407.112.07 / 12.60card 15.76OK
ref2va

2 character images + 5.17 s clip, reference video at 448

FP8 · PAI 8768×448 · 124 fdit5080-ref2va-fp8-pai8
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
223.9Compute220.3297.28.24 / 10.40card 12.85OK
ref2va

2 character images + 6.58 s clip, reference video at 448

FP8 · PAI 8768×448 · 158 fdit5080-ref2va-fp8-pai8
DGX Spark (GB10)RTX 5080RTX 3060PC CPU
282.3Compute278.4365.79.01 / 11.25card 14.41OK
ref2va

2 character reference images (transparent PNG)

FP8 · PAI 8768×448 · 124 fdit5080-ref2va-fp8-pai8
DGX Spark (GB10)RTX 3060RTX 5080PC CPU
117.2Compute114.6186.16.43 / 10.13card 12.37OK
ref2va

1 reference image + reference video with audio

FP8 · PAI 8768×448 · 124 fdit5080-ref2va-fp8-pai8
DGX Spark (GB10)RTX 3060RTX 5080PC CPU
293.6Compute290.7541.39.15 / 11.31card 13.60OK
fl2va

1 first-frame image

FP8 · PAI 8768×448 · 124 fdit-5080
DGX Spark (GB10)RTX 3060RTX 5080PC CPU
39.068.3Not measuredOK

Times in seconds, VRAM in GiB (2^30 bytes). Steps that run at the same time (video and audio decode, reference video and audio encode) overlap, so the steps add up to more than the total.

Images: Qwen-Image 2.1

The image pipeline gets its own table because its steps and units differ. Every GPU step runs on the RTX 5080; compositing runs on the CPU.

6 featured rows of 23 ·

Images: Qwen-Image 2.1
RunPipeline and InputsDiT VariantSteps and Devicess?wall / Computes?GiB?allocated / reservedcardStatus
t2i

Text prompt (original character)

BF16 · 40 steps1152×672qimg-dit-bf16-5080-streamstream
RTX 5080PC CPU
≈23.026.0Not reportedOK
t2i

Text prompt (original character)

BF16 · 40 steps1152×672qimg-dit-bf16-5080-streamstream
RTX 5080PC CPU
≈23.026.9Not reportedOK
t2i

Text prompt (original character)

BF16 · 40 steps1152×672qimg-dit-bf16-5080-streamstream
RTX 5080PC CPU
≈23.025.9Not reportedOK
t2i

Text prompt (original character)

BF16 · 40 steps1152×672qimg-dit-bf16-5080-streamstream
RTX 5080PC CPU
≈23.025.8Not reportedOK
t2i

Text prompt (ceramic cup)

GGUF Q4_K_M · 40 steps1024×1024qimg-dit-gguf-5080gguf
RTX 5080PC CPU
38.641.25.07 / 5.59card —OK
t2i

Text prompt (ceramic cup)

BF16 · 40 steps1024×1024qimg-dit-bf16-5080-streamstream
RTX 5080PC CPU
33.047.91.56 / 5.88card 9.19OK

Failures, Listed as Failures

These runs failed or were canceled. The time spent before they stopped is listed too.

RunWhatCodeFailed AtUntil Stop
Exp. 01Failed to loadref2va · NF4 · Turbo 4dit5080-ref2va-nf4-lx42 character reference images (transparent PNG)RUNTIME_ERRORDiT loadRTX 5080Not run
Exp. 02 · 9d7d9e6f · R3bOut of GPU memoryref2va · INT8 · Turbo 4dit5080-ref2va-int8-lx42 character images + 5.17 s reference clip with audioGPU_OOMDiT denoiseRTX 5080323.9 s
Exp. 05 · 58da16b6Out of GPU memoryref2va · FP8 · PAI 8dit5080-ref2va-fp8-pai82 character images + 5.88 s clipGPU_OOMDiT denoiseRTX 5080118.0 s
Exp. 01Failed to loadref2va · NF4 · Turbo 8dit5080-ref2va-nf4-lx82 character reference images (transparent PNG)RUNTIME_ERRORDiT loadRTX 5080Not run
Exp. 01Failed to loadref2va · NF4 · Original 50-stepdit5080-ref2va-nf4-base2 character reference images (transparent PNG)RUNTIME_ERRORDiT loadRTX 5080Not run
Exp. 02 · 7fa18f97 · R3Invalid settingref2va · INT8 · Turbo 4dit5080-ref2va-int8-lx42 character images + 5.17 s reference clip with audioINVALID_ARGUMENTDiT denoiseRTX 5080287.3 s
Exp. 02 · 9597890a · R6Invalid settingref2va · INT8 · Turbo 4dit5080-ref2va-int8-lx42 character images + 5.17 s reference clip with audioINVALID_ARGUMENTDiT denoiseRTX 5080281.4 s
Exp. 02 · 07156692 · R6bCanceledref2va · INT8 · Turbo 4dit5080-ref2va-int8-lx42 character images + 5.17 s reference clip with audioCANCELLEDReference encode (video VAE)RTX 3060201.1 s
Exp. 05 · f612bb72Out of GPU memoryref2va · FP8 · PAI 8dit5080-ref2va-fp8-pai83 character images (third is a duplicate) + 5.17 s clipGPU_OOMDiT denoiseRTX 5080131.7 s
Exp. 05 · 3ae8e653Out of GPU memoryref2va · INT8 · Turbo 4dit5080-ref2va-int8-lx4-fixed3 character images (third is a duplicate) + 5.17 s clipGPU_OOMDiT denoiseRTX 5080133.5 s
Exp. 09 · dc6453d1 · E1Invalid settingref2va · FP8 · PAI 8dit5080-ref2va-fp8-pai82 character reference images (transparent PNG)INVALID_ARGUMENTVideo decodeRTX 5080236.8 s
Exp. 12 · f16484ffRefused at admissiont2i · BF16 · 40 stepsqimg-dit-bf16-5080-phaseText prompt (ceramic cup)422DiT denoiseRTX 508014.4 s
Exp. 12 · 03261cb0Out of GPU memoryt2i · BF16 · 40 stepsqimg-dit-bf16-5080-streamText prompt (ceramic cup)GPU_OOMVAE decodeRTX 508043.5 s
Exp. 12 · 5c0a3c90Refused at admissioni2i · BF16 · 40 stepsqimg-dit-bf16-5080-streamText prompt + reference images422VAE decodeRTX 508049.7 s
Exp. 12 · 947ed5baRefused at admissioni2i · GGUF Q4_K_M · 40 stepsqimg-dit-gguf-5080Text prompt + reference images422DiT denoiseRTX 5080Not run
Exp. 12 · 3e8b52deOut of GPU memoryi2i · BF16 · 4 stepsqimg-dit-bf16-5080-streamText prompt + reference imagesGPU_OOMVAE decodeRTX 508020.1 s

Download the data

The same rows as the tables, without hostnames or file paths. Seconds are wall time unless a column says compute; VRAM is in GiB.

Six Clips, Four Stills

Made on 2026-10-18 with an original character, The Courier, through the controller API’s production routes (t2i-pc, fl2va-pc and ref2va-pc). Each was a single run; the times are the controller’s step times.

Measured 2026-10-18Single run eachWeb copy is loudness-normalized; the raw output is about −37 to −50 LUFS, AAC 32 kHz.

AI-generated · Powered by MiniMax H3

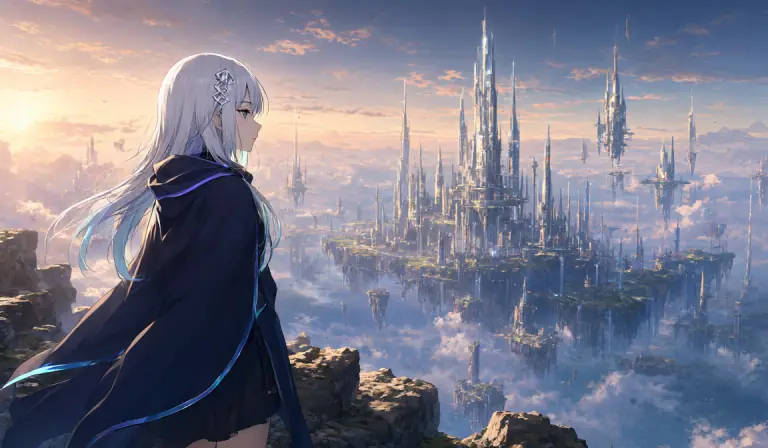
Cliff at Dawn

76.0 sEnd to end

fl2varun 82d036a7dit-5080Seed 101

  • Text encode· DGX Spark (GB10)2.3 s
  • First-frame encode (video VAE)· RTX 50806.1 s
  • DiT denoise· RTX 508038.7 s
  • Video decode· RTX 508027.7 s
  • Audio decode· RTX 30605.8 s
  • Mux· PC CPU0.5 s

Sound (generated by H3): High wind rushing past, fluttering fabric, distant waterfalls

AI-generated · Powered by MiniMax H3

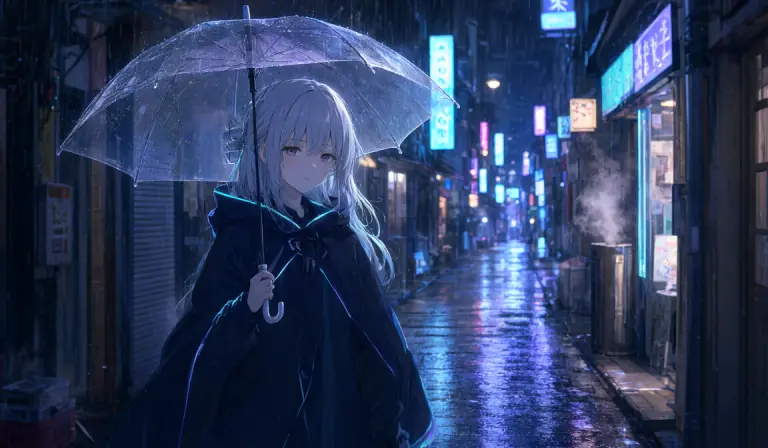
Neon Rain

57.2 sEnd to end

fl2varun cfa759dfdit-5080Seed 202

  • Text encode· DGX Spark (GB10)1.3 s
  • First-frame encode (video VAE)· RTX 50801.1 s
  • DiT denoise· RTX 508032.0 s
  • Video decode· RTX 508022.4 s
  • Audio decode· RTX 30600.9 s
  • Mux· PC CPU0.3 s

Sound (generated by H3): Steady rain, dripping awnings, footsteps through puddles, a faint neon hum

AI-generated · Powered by MiniMax H3

Aurora Sea

57.4 sEnd to end

fl2varun 72341805dit-5080Seed 303

  • Text encode· DGX Spark (GB10)1.4 s
  • First-frame encode (video VAE)· RTX 50801.0 s
  • DiT denoise· RTX 508031.7 s
  • Video decode· RTX 508022.8 s
  • Audio decode· RTX 30600.9 s
  • Mux· PC CPU0.3 s

Sound (generated by H3): Waves lapping on rock, a soft sea breeze, crystalline chimes

AI-generated · Powered by MiniMax H3

Close-Up

58.6 sEnd to end

fl2varun 7d52714adit-5080Seed 404

  • Text encode· DGX Spark (GB10)1.3 s
  • First-frame encode (video VAE)· RTX 50801.0 s
  • DiT denoise· RTX 508033.2 s
  • Video decode· RTX 508022.5 s
  • Audio decode· RTX 30600.7 s
  • Mux· PC CPU0.4 s

Sound (generated by H3): A soft hush of air, a delicate shimmer, a quiet breath

AI-generated · Powered by MiniMax H3

Rooftop Leap

108.0 sEnd to end

ref2varun f083d166dit5080-ref2va-fp8-pai8Seed 505

  • Text encode· DGX Spark (GB10)8.5 s
  • Reference encode (video VAE)· RTX 50805.7 s
  • Reference audio encode· RTX 30601.7 s
  • DiT denoise· RTX 508070.0 s
  • Video decode· RTX 508022.8 s
  • Audio decode· RTX 30601.0 s
  • Mux· PC CPU0.5 s

Sound (generated by H3): Rushing wind, quick footsteps on concrete, a snapping cloak, a soft landing, birds taking off

AI-generated · Powered by MiniMax H3

Hilltop Meadow

105.0 sEnd to end

ref2varun 5adf4237dit5080-ref2va-fp8-pai8Seed 606

  • Text encode· DGX Spark (GB10)8.3 s
  • Reference encode (video VAE)· RTX 50805.5 s
  • Reference audio encode· RTX 30601.5 s
  • DiT denoise· RTX 508068.0 s
  • Video decode· RTX 508022.5 s
  • Audio decode· RTX 30600.9 s
  • Mux· PC CPU0.3 s

Sound (generated by H3): A warm breeze, rustling grass, distant birdsong, a crystalline ring

AI-generated · Qwen-Image 2.1The ref2va Reference
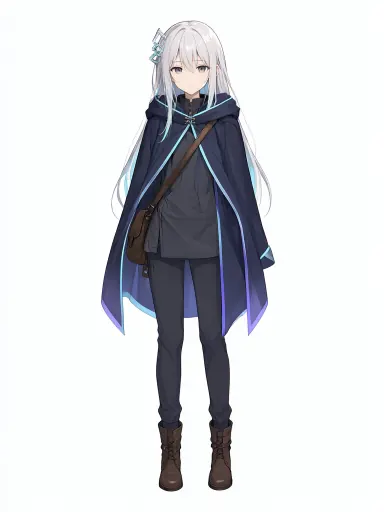
The ref2va ReferenceThe character sheet itself was generated the same day with Qwen-Image 2.1 (t2i-pc): 26.0–26.1 s per run, 36.6 s with a cold text encoder.

Qwen-Image 2.1 Stills

AI-generated · Qwen-Image 2.1

1152×672, 40 steps. Text encode, DiT and VAE run on the RTX 5080; compositing on the CPU. These stills were also the first frames for fl2va.

  • Cliff at DawnCliff at Dawn26.0 srun 3a6d932d
  • Neon RainNeon Rain26.9 srun 0e2463b8
  • Aurora SeaAurora Sea25.9 srun d47c0fa1
  • Close-UpClose-Up25.8 srun 577fc7a4

40 DiT Variants, One RTX 5080

Same text conditioning, same reference latents, same seed — only the DiT component changed. 40 DiT variants benchmarked; 37 produced video; 3 NF4 variants failed to load. Every DiT that loaded ran on the RTX 5080 with layer streaming.

Findings

  • Speed is set by the schedule first and quantization second: at the same schedule INT8 is 3.6–10.2% faster than FP8, BF16 is 1.6–2.0× slower, and the original 50 steps are 6.0–6.4× slower than PAI 8 (denoise compute).
  • Fastest text-only: INT8 PAI 8 (DiT 33.2 s, denoise 26.0 s); dit-5080 in production (FP8 PAI 8) takes 37.8 s / 28.9 s. Fastest with references: INT8 Turbo 4 (83.9 s / 74.4 s); production FP8 PAI 8 takes 120.9 s / 115.5 s.
  • Exp. 01 measured each variant’s first call after a cold load, on 2026-10-17. The production runs on 2026-10-18 are fl2va calls on an already loaded DiT: 31.7–38.7 s (31.7–33.2 s once warm), versus 37.8 s for the same dit-5080 here. Compare rows within one experiment, not across experiments.
  • AdaLN mode and release after use (host/drop) do not change the output — decoded MD5s match — but online AdaLN adds 23–32 s per call outside the steps (fixed 2–8 s, off 2–3 s).
  • With references, PAI 8 and Turbo 8 paste the black-background reference into the clip (21–22 and 37–43 of 124 frames); Turbo 4 and the original schedule show none. All three NF4 variants failed to load: the quantized weights lack comfy_quant metadata and the pinned loader rejects them.

Every Variant, Sorted by DiT Time

View as

Bright blue marks the DiT used in production; the rest are controls on the same RTX 5080.

  • Denoise compute · In production
  • Denoise compute
  • DiT stage (wall)
  • dit5080-fl2va-int8-pai8INT8 · PAI 8
  • dit5080-fl2va-fp8-pai8-dropFP8 · PAI 8 · drop
  • dit-5080FP8 · PAI 8 · In production
  • dit5080-fl2va-int8-lx4INT8 · Turbo 4
  • dit5080-fl2va-fp8-pai8-sdpaFP8 · PAI 8 · SDPA (exact)
  • dit5080-fl2va-fp8-lx4FP8 · Turbo 4
  • dit5080-fl2va-int8-lx8INT8 · Turbo 8
  • dit5080-fl2va-fp8-lx8FP8 · Turbo 8
  • dit5080-fl2va-bf16-pai8BF16 · PAI 8
  • dit5080-fl2va-bf16-pai8-adalnoffBF16 · PAI 8 · SDPA (exact) · AdaLN off
  • dit5080-fl2va-bf16-pai8-sdpaBF16 · PAI 8 · SDPA (exact)
  • dit5080-fl2va-bf16-lx4BF16 · Turbo 4
  • dit5080-fl2va-bf16-lx4-sdpaBF16 · Turbo 4 · SDPA (exact)
  • dit5080-fl2va-bf16-lx8BF16 · Turbo 8
  • dit5080-fl2va-int8-base-subblockINT8 · Original 50-step · SubBlock
  • dit5080-fl2va-int8-baseINT8 · Original 50-step
  • dit5080-fl2va-fp8-baseFP8 · Original 50-step
  • dit5080-fl2va-int8-base-sdpaINT8 · Original 50-step · SDPA (exact)
  • dit5080-fl2va-fp8-base-sdpaFP8 · Original 50-step · SDPA (exact)
  • dit5080-fl2va-bf16-baseBF16 · Original 50-step
  • dit5080-fl2va-bf16-base-exact-adalnoffBF16 · Original 50-step · Official precision · AdaLN off
  • dit5080-fl2va-bf16-base-exactBF16 · Original 50-step · Official precision

Solid: the recorder’s denoise-loop compute. Pale: the rest of the DiT stage’s wall time (AdaLN prep, input assembly, release). Numbers read wall · compute, in seconds.Each bar is a variant’s first call after a cold load (2026-10-17). The production runs on 2026-10-18 call an already loaded DiT: 31.7–38.7 s (31.7–33.2 s once warm), so they can beat this chart’s fastest cold call, 33.2 s.

Side by Side

Four tiles play in sync; the labels are drawn by the page, not burned into the video. Same prompt, seed 42, 768×448, 124 frames.

AI-generated · Powered by MiniMax H3
  1. ↖FP8 · PAI 8dit-508037.8 s
  2. ↗FP8 · Turbo 8dit5080-fl2va-fp8-lx857.8 s
  3. ↙FP8 · Turbo 4dit5080-fl2va-fp8-lx444.6 s
  4. ↘FP8 · Original 50-stepdit5080-fl2va-fp8-base193.3 s

Sound comes from the top-left tile (generated by H3; no dialogue). Loudness-normalized for the web.

Drag to Compare: Production vs. Official Precision

Left: dit-5080 as used in production (FP8, PAI 8; DiT 37.8 s). Right: BF16, original 50-step, exact attention (413.5 s). Both clips play in sync. Loudness-normalized for the web.

FP8 · PAI 8 · 37.8 sBF16 · original 50 · 413.5 s
AI-generated · Powered by MiniMax H3

Where the Time Goes with References

ref2va carries the reference video, the reference images and Qwen’s vision tokens into the DiT sequence. The longer the sequence, the slower each step — and not linearly.

Three Runs on a Timeline, Colored by Device

View as

Steps that run at the same time sit one above the other. Gray hatching is time between steps that no step owns (scheduling and transfers).

  • DGX Spark (GB10)
  • RTX 5080
  • RTX 3060
  • PC CPU
  • Unattributed (scheduling, transfers)

Reference Video 768 → 448: Time

View as

R5’s conditions, with only the reference video’s preprocessing short edge changed from 768 to 448. The output stays 768×448.

  • 768
  • 448
One segment, total
297.2600.5
DiT
223.9470.7
Reference video encode
28.673.7
Text encode
21.329.0
Denoising step p50
27.557.9

DiT torch allocated / reserved 11.15 / 12.54 → 8.24 / 10.40 GiB; DiT sequence 80,832 → 52,544 rows.

No video in this section: the swap experiments used a third-party reference clip, so nothing derived from it is published. The numbers are.

Method and Caveats

How the numbers were measured, how to read them, and what they cannot tell you.

DiT stage (wall)
From the start to the end of the DiT stage (all denoising steps), including AdaLN prep, input assembly and release. This page uses it by default.
Denoise compute
The recorder’s h3.denoise_av.compute_ms: the denoising loop only. Older reports quote it, so it appears as a secondary column.
End to end
Wall time from run creation to completion. Listed only when every step ran in that run; rows that reuse steps from another run say “Not end to end.”
Device
Each step’s device comes from the run record’s node and resource group. If the archive lacks it, the step says “Placement not recorded” — never a guess.
GiB and GB
RTX 5080 and RTX 3060 memory is always GiB (2^30 bytes). All DGX Spark memory figures (meminfo and its torch peaks) use GB (10^9 bytes) and are labeled.
torch and NVML
Allocated / reserved are the DiT process’s PyTorch peaks. Whole-card NVML is sampled at 2 Hz, includes other processes’ CUDA contexts, and is a lower bound.
  • Most scenarios use one prompt and one seed; the DiT benchmark measures the first call after a cold load.
  • Image metrics are objective proxies, not a verdict on how good a clip looks; leaks and copy-through are graded by eye.
  • Where a third character appears, its image duplicates the second: memory and time only.
  • The 2026-10-18 runs are single runs, and their VRAM was not logged.

Not published: the third-party reference clip used in the swap experiments and everything derived from it, screenshots of the pre-rename UI, and raw records that contain paths or hostnames.

Source code and architecture notes — coming soon

Glossary

What the labels in the tables and charts mean.

DiT
The diffusion transformer at the heart of H3 and Qwen-Image. It turns noise into the picture over a series of denoising steps and is usually the heaviest stage of a run.
DiT stage vs. denoising step
The DiT stage is the whole DiT call: every denoising step plus setup and release. A denoising step is one pass of that loop; “step p50” is the median time of one.
PAI 8
Alibaba PAI’s official 8-step acceleration LoRA for MiniMax H3 (MiniMax-H3-FL2VA-Acc-8Step and -Ref2VA-Acc-8Step), trained with Parallel Decoding Distillation; rank 64, BF16.
Turbo 8 / Turbo 4 (lx8 / lx4)
LightX2V’s MiniMax H3 Turbo LoRAs for 8 and 4 denoising steps (“lx” in component IDs): fl2v 8-step v1.0 and 4-step v1.2 (768p), ref2v 8-step v1.0 (768p) and 4-step v0.1.
Original 50-step
The base MiniMax H3 checkpoint with no acceleration LoRA: 50 denoising steps.
BF16, FP8, INT8, NF4
The number format of the DiT’s weights: BF16 (16-bit, the official precision), FP8 and INT8 (8-bit), NF4 (4-bit). Lower precision needs less memory; all three NF4 builds failed to load.
AdaLN online / fixed / off
How the DiT gets its per-step AdaLN modulation. Fixed reads precomputed plans from a sidecar file built for that LoRA and step count (here the PAI LoRAs, and Turbo 4 in experiment 04); online rebuilds them from the weights on every call; off computes them inside every block at every step. The decoded output was identical in all three.
SDPA (exact)
Attention computed with PyTorch’s scaled-dot-product attention instead of the default FP8 attention. With BF16 weights and no LoRA, it reproduces the official precision.
SubBlock
Sparse attention over sub-blocks of the token sequence (the upstream subblock_sparse_attn). It is an approximation.
host / drop
What happens to the DiT’s weights after a call. host frees the GPU copy and keeps the weights in pinned host RAM, so the next call copies them straight back; drop frees them, so the next call loads them again. The output did not change.
Layer streaming
Every DiT on the RTX 5080 streams its blocks from pinned host memory (block offload, prefetch 1, pinned cap 24 GiB). That is how a 16 GB card runs a DiT larger than its memory.
fl2va DiTs in t2va rows
Text-only (t2va) runs use the FL2VA DiT variants: the FL2VA checkpoint serves both text-only and first-frame tasks, and its AdaLN sidecar covers both.

Definitions come from the Phasyn Studio repository (component catalogue and runtime notes, commit c5d9310; the source is not public yet) and the two LoRA model cards.

Test Environment

Read from the machines on 2026-10-19; the runs on this page are from 2026-10-17 and 2026-10-18. Anything that could not be read says “Not recorded.”

Software

Phasyn Studio
commit c5d9310 (2026-10-18)
PyTorch
2.14.1+cu130 (CUDA 13.0, cuDNN 9.24) with Python 3.12.14 in every PC runtime; the GB10 runtime’s lock file pins the same build
NVIDIA driver (PC)
615.71.09 (CUDA driver 13.4)
OS (PC)
Debian GNU/Linux 13, Linux 6.12
DGX Spark OS, driver and CUDA
Not recorded

Weights

MiniMax H3
MiniMaxAI/MiniMax-H3, revision 42ed227
PAI 8 LoRA
alibaba-pai/MiniMax-H3-Acc-LoRAs (FL2VA and Ref2VA Acc 8-step)
Turbo LoRAs
lightx2v/Minimax-h3-Turbo: fl2v 8-step v1.0, fl2v 4-step v1.2, ref2v 8-step v1.0, ref2v 4-step v0.1
Qwen-Image 2.1
Qwen/Qwen-Image-2.1, revision d26bb61
Qwen3-VL-4B (image to prompt)
snapshot ebb281e

Hardware

CPU (PC)
Intel Core i9-13900K, 24 cores / 32 threads
RAM (PC)
62.6 GiB
RTX 5080
16 GB, PCIe 5.0 ×16
RTX 3060
12 GB, PCIe 4.0 ×4 link
DGX Spark
GB10, 128 GB unified memory
Network
PC to DGX Spark: 1 GbE on the PC side, through a router; ping about 1.2 ms

13 Experiments

The question, method, findings and caveats of each experiment. Its numbers are in the speed table above.

  1. 01DiT Benchmark: 40 H3 DiT VariantsWhich DiT variant is fastest and lightest on VRAM, and do quantization, acceleration and AdaLN settings change the output?2026-10-17

    With the same text conditioning, reference latents and seed (42), only the DiT component changed: FP8/INT8/BF16/NF4 × original 50-step/PAI 8/Turbo 8/Turbo 4, plus attention and AdaLN settings, text only (t2va) and with two character images (ref2va), at 768×448 and 124 frames. Every DiT that loaded ran on the RTX 5080 with layer streaming. 40 DiT variants benchmarked; 37 produced video; 3 NF4 variants failed to load. Text encoding ran once on te-gb10 on the DGX Spark and was shared.

    Findings

    • Speed is set by the schedule first and quantization second: at the same schedule INT8 is 3.6–10.2% faster than FP8, BF16 is 1.6–2.0× slower, and the original 50 steps are 6.0–6.4× slower than PAI 8 (denoise compute).
    • Fastest text-only: INT8 PAI 8 (DiT 33.2 s, denoise 26.0 s); dit-5080 in production (FP8 PAI 8) takes 37.8 s / 28.9 s. Fastest with references: INT8 Turbo 4 (83.9 s / 74.4 s); production FP8 PAI 8 takes 120.9 s / 115.5 s.
    • Exp. 01 measured each variant’s first call after a cold load, on 2026-10-17. The production runs on 2026-10-18 are fl2va calls on an already loaded DiT: 31.7–38.7 s (31.7–33.2 s once warm), versus 37.8 s for the same dit-5080 here. Compare rows within one experiment, not across experiments.
    • AdaLN mode and release after use (host/drop) do not change the output — decoded MD5s match — but online AdaLN adds 23–32 s per call outside the steps (fixed 2–8 s, off 2–3 s).
    • With references, PAI 8 and Turbo 8 paste the black-background reference into the clip (21–22 and 37–43 of 124 frames); Turbo 4 and the original schedule show none. All three NF4 variants failed to load: the quantized weights lack comfy_quant metadata and the pinned loader rejects them.

    Caveats

    • One prompt and one seed per scenario; only the first call after loading was measured, and load times depend on the page cache.
    • Text and reference encodes ran once and were reused, so each row’s run time covers DiT + decode + mux only, not end to end.
    • The two reference images were transparent PNGs whose transparent areas turn black at input, which makes the pasting very visible.
    40 rows in the speed table →
  2. 02Character Swap Runs R1–R6Can two character images replace the two characters in a reference clip, which prompt works, and how long does it take?2026-10-18

    ref2va-pc: text encode on te-gb10 on the DGX Spark, reference video encode on the RTX 5080 (the R3/R6 series on the RTX 3060), reference audio encode and audio decode on the RTX 3060, DiT and video decode on the RTX 5080. The runs compared prompt wording, transparent versus white-background images, and PAI 8 versus Turbo 4 (seed 42, 768×448, 124 frames).

    Findings

    • Prompt v1 (reference video fully_preserved) copied the original characters’ looks (R1, R2); v2 treated the video as a weak_reference for camera and motion only and spelled out the costume change, which replaced both characters (R5).
    • PAI 8 with two images and a 5.17-second clip: DiT 456.6–480.6 s, full run 581.8–607.4 s. The DiT sequence is 79,296–80,832 rows, about 2.3× the images-only case (35,136).
    • Reference video encode took about 71.9–73.7 s on venc-5080 and 247.6–250.2 s on venc-3060, so production moved it to the RTX 5080.
    • Turbo 4 failed: R3 and R6 were rejected by the LoRA sampling contract because the pipeline pinned 8 steps (INVALID_ARGUMENT); R3b ran out of GPU memory in the DiT (needed 1.08 GiB more, 1.07 GiB free); R6b was canceled mid-run.

    Caveats

    • Single seed; swap quality was judged by eye.
    • The R3 series encoded the reference video on the RTX 3060, so those venc times are not comparable with R1, R2 and R5.
    • te-gb10 still held two copies of the text encoder in these runs (fixed in experiment 11), so its memory figures are inflated.
    7 rows in the speed table →
  3. 03VAE: Resident vs. On DemandShould the video VAE processes on the RTX 5080 stay loaded, or start only when needed?2026-10-18

    vae-5080 (video decode) and venc-5080 (reference video encode) keep their weights in pinned host memory and copy them to the GPU on each call. Three setups — both resident, only venc stopped, both stopped — were compared on cold starts, first versus warm calls, DiT speed and free memory.

    Findings

    • Loading on demand adds about 24–27 s per render (an estimate: cold starts are 11.9–15.8 s for vae-5080 and 8.6–10.7 s for venc-5080, and a first call adds 1.1–1.8 s to decode and 0.8 s to encode).
    • DiT speed did not change (denoise 463.2 s versus 463.8–464.3 s resident) and the latents were bit-identical; the only gain was host memory free during the DiT, 19.1 → 34.3 GiB, so the VAEs stay resident.
    • Turbo 4 (online AdaLN) with a reference video fit only with both VAEs stopped: DiT 252.8 s with about 0.3 GiB of the card left; with only venc stopped it ran out of GPU memory.

    Caveats

    • The 24–27 s figure adds up separate cold-start and first-call measurements; it is not one end-to-end run.
    • “Resident” means the process and its CUDA context (about 0.9 GiB each) stay on the 5080; the weights still move to the GPU on every call.
  4. 04Turbo 4 with Fixed AdaLNWith a precomputed AdaLN, does Turbo 4 fit on the RTX 5080 next to both resident VAEs, and does the output change?2026-10-18

    A 465 MB precomputed AdaLN sidecar was built for Turbo 4 (INT8, lx4 LoRA) so it no longer computes AdaLN online. Under the R2 and R5 conditions the runs measured VRAM and DiT time and compared the latents value by value with the online version.

    Findings

    • It fits with both VAEs resident: DiT 229.3–235.3 s (PAI 8 takes about 470 s); torch allocated/reserved 11,644/13,070 MiB (PAI 8: 11,418/12,842), real headroom 1.40 versus 1.61 GiB.
    • The latents are identical to the online version (1,193,472 video values and 13,248 audio values, max difference 0).
    • Quality: seed 42 already leaks the original character’s white frilled skirt (experiment 08 confirms it on 4 of 4 seeds), so ref2va-pc stays on PAI 8.

    Caveats

    • Text and reference encodes were reused from R2/R5, so these times cover the DiT (plus decoding under R5) only.
    2 rows in the speed table →
  5. 05Swap Limits with a 768 Reference VideoWith a 768 reference video, how many frames and characters per segment fit on the RTX 5080?2026-10-18

    The full ref2va-pc route ran in the production setup with both VAEs resident (seed 42), testing three characters at 124 frames and two at 141 frames for PAI 8 and Turbo 4 fixed. The third character image duplicates the second, so it tests memory and time only.

    Findings

    • PAI 8: two characters at 124 frames works (headroom 1.61 GiB); three at 124 frames ran out of GPU memory (the FFN needed 2.49 GiB with 2.24 GiB free), and so did two at 141 frames (needed 2.34 GiB contiguous; 1.55 GiB free plus 1.71 GiB fragmented).
    • Turbo 4 fixed: three characters at 124 frames ran out of memory; two at 141 frames succeeded (DiT 269.9 s, headroom 0.695 GiB) — but see experiment 08 for its quality problem.
    • All three failures hit at the very start of the DiT (0 steps done), yet text and reference encodes run first, so each failed run still took 118.0–133.5 s.

    Caveats

    • The third character is a duplicate image: it speaks to memory and time, not real three-character quality.
    • The out-of-memory boundary depends on fragmentation, so other inputs may land differently.
    4 rows in the speed table →
  6. 06Reference Video at 448What happens to speed, VRAM and quality when the reference video is preprocessed at 448 instead of 768?2026-10-18

    Under R5’s conditions (PAI 8, two characters, 124 frames, seed 42), only the reference video’s preprocessing short edge changed from 768 to 448 (1280×720 → 800×448); the output stays 768×448. The runs also confirmed that a 768 control matches R5 bit for bit and that the Studio UI and MCP produce identical results.

    Findings

    • One segment went from 600.5 to 297.2 s; DiT 470.7 → 223.9 s (57.9 → 27.5 s per denoising step, p50); reference video encode 73.7 → 28.6 s; DiT sequence 80,832 → 52,544.
    • DiT torch allocated/reserved dropped from 11.15/12.54 GiB to 8.24/10.40 GiB.
    • Quality (one seed): characters and costumes hold and the cut lands at the same point; motion is calmer (median frame-to-frame change 3.02 versus 4.02, source 6.22) and mouth movement is smaller.
    • The 768 control’s latents and decoded video match R5 bit for bit, and the 448 results from the Studio UI and from MCP are bit-identical.

    Caveats

    • Quality was checked on one seed only; whether 448 leaks costumes on other seeds is untested.
    • R5’s text encode was a warm call while the 768 control hit the first call after a restart (79.9 s), so totals are compared against R5.
    3 rows in the speed table →
  7. 07Swap Limits at 448With a 448 reference video, how long can a segment be and how many characters fit?2026-10-18

    With a 448 reference video, PAI 8 and seed 42 in the production setup, the runs tested two characters at 124, 141 and 158 frames and three at 124 frames, then fitted a VRAM model to the five successful points. The third character image is a duplicate.

    Findings

    • Everything succeeded: two characters at 124/141/158 frames (DiT 223.9/257.4/282.3 s, totals 297.2/339.6/365.7 s) and three at 124 frames (322.5/411.2 s), with headroom of 4.52/4.16/3.76/3.20 GiB.
    • VRAM model: allocated peak ≈ 2,892 MiB + 0.1056 MiB × sequence length (residuals under 35 MiB across five points); 1.6 GiB of headroom has proven safe, 0.8 GiB has not.
    • The limits are wired into One-Click Character Swap: up to 158 frames per segment for one or two characters and 124 for three. The 141-frame output copied the source’s subtitle-removal blur into shot 1.

    Caveats

    • The third character is a duplicate; lengths of 175 frames and up are model predictions, not measurements, so this page does not plot them.
    3 rows in the speed table →
  8. 08Turbo 4 Across Four SeedsDoes Turbo 4 leak the original character’s costume every time?2026-10-18

    Under R5’s conditions (768 reference video, two characters, 124 frames), seeds 42, 7, 1234 and 31337 compared PAI 8 with Turbo 4 fixed. Seed 42 is a full pipeline run; the other seeds reuse R5’s conditioning and rerun only the DiT and decoding.

    Findings

    • Turbo 4 leaked the original white frilled skirt on 4 of 4 seeds and copied the subtitle-removal blur on 4 of 4; PAI 8 leaks too (1 clear, 2 faint, 1 clean) but copied the blur on 0 of 4.
    • Speed: PAI 8 DiT 465.8–472.6 s, Turbo 4 229.2–235.5 s.
    • Decision: ref2va-pc stays on PAI 8 with no Turbo 4 draft route; for speed, use PAI 8 with a 448 reference video (DiT 224 s).

    Caveats

    • Four seeds are not a failure rate; leak severity is a visual grade (none / faint / clear).
    6 rows in the speed table →
  9. 09Checking an External Reference-Cost AnalysisAn outside analysis blamed reference media for slow ref2va runs. Is it right, and where does the cost really go?2026-10-18

    The external analysis was checked claim by claim against the code, run records and payloads: R1’s DiT sequence was broken down, eight runs were used to fit step time against sequence length, and the baseline runs E1–E4 from 2026-10-17 are listed.

    Findings

    • Broadly right, but R1’s main cost is the reference video, not the images: of 79,268 rows, reference video 37,296 (47%), Qwen vision 16,944 (21%), reference images 10,880 (14%), target video 12,432 (16%), text and audio 1,716.
    • Step-time model: step(L) ≈ 1.68e-4·L + 6.81e-9·L² seconds, within about ±3% from 13k to 81k rows (RTX 5080, FP8 PAI 8).
    • Errors in the report: video decoding is actually FP32, and aenc’s 6.98 s was mostly waiting on the same file download. A two-step text encode, cost records and the reference_video_short_edge parameter (experiment 06) are now implemented.

    Caveats

    • The time model applies only to the RTX 5080, FP8 PAI 8 and a 768×448×124 target; “reusing the conditioning when only the seed changes saves about 100 s” is an estimate, not yet implemented or measured.
    5 rows in the speed table →
  10. 10Front End and MCP Field TestWhat breaks when a full experiment is run by hand through the UI and through MCP?2026-10-18

    Experiment 06’s 448 run was prepared and executed through the installed MCP and through the Studio UI, logging every problem found and comparing the two paths’ outputs.

    Findings

    • Phase 1 found 26 issues, 3 of them major (MCP dropped large outputs, run inputs were not visible, the inference page ordered materials differently from Studio); all are fixed.
    • Phase 2 found 7 new items, including latent hashes that include load metadata, cold calls of the audio component that are not numerically reproducible, and a first text encode about 50 s slower after a restart; 2 are fixed.
    • The 448 results from the UI and from MCP are bit-identical.

    Caveats

    • The screenshots show the pre-rename UI, so they are not published; the site’s walkthrough videos are recorded separately in the English UI.
  11. 11Reverse Prompt Memory on DGX SparkCan image reverse prompting run on the DGX Spark next to the resident text encoder te-gb10?2026-10-18

    Image reverse prompting (qimg-vision-gb10, Qwen3-VL-4B BF16) moved to the DGX Spark next to te-gb10. After fixing the deployment, the runs measured memory, load and call times, and fixed te-gb10 loading a duplicate text encoder after a ref2va call.

    Findings

    • Before the fix, te-gb10 loaded a second, identical text encoder after a ref2va call, using 51.5 GB more. With sharing there is one copy: the ref2va call peaks at 56.81/59.66 GB allocated/reserved and settles at 51.69/52.30 GB, and the output matches R5 bit for bit.
    • The GB10 uses unified memory, so available capacity is MemAvailable − 4 GiB (64.10 GB), not torch’s mem_get_info, which reports only 8.53 GB because it ignores reclaimable page cache.
    • The 4B reverse-prompt model loads in 62.5 s, captions in 5.3 s and analyzes in 85.8 s; next to te-gb10, MemAvailable bottomed at 57.29 GB, and keeping it resident costs about 11.6 GB.

    Caveats

    • DGX memory figures are in GB (10^9 bytes); te-gb10’s ref2va peak with both models resident is only estimated, not measured.
    • The caption contained errors (it called horizontal throwing lines vertical stripes); quality was checked on a single image.
    2 rows in the speed table →
  12. 12Image Generation Check (Qwen-Image 2.1)Does Qwen-Image 2.1 on the RTX 5080 match the author’s earlier image tool, DiT Studio, and does it fit while the video components stay resident?2026-10-18

    The first GPU validation ran 30 runs (28 via the API, 2 via Image Studio). It compared eight historical cases pixel for pixel and measured time and VRAM for three DiT components (BF16 phase, BF16 stream and Qwen-Image GGUF Q4_K_M), full versus tiled VAE decoding, and the cost of intermediate previews. Every GPU step ran on the RTX 5080; compositing on the CPU.

    Findings

    • All eight cases match DiT Studio’s output pixel for pixel in RGBA (max difference 0); BF16 phase and stream latents are bit-identical, and batch and UI images match single runs.
    • At the time only the GGUF route finished in the production state: BF16 phase was refused at admission (needed 14.77 GiB, 11.66 GiB available), and BF16 stream finished its DiT (32.5–33.2 s at 1024²) but then ran out of memory in VAE decoding, because the text encoder and DiT did not release the CUDA cache after their calls.
    • VAE decoding at 1024² full takes 0.74–0.79 s (7.05 GiB allocated); tiled decoding shows thin pink vertical lines; 1536² full is not feasible on a 16 GB card.
    • Intermediate previews (every 4 steps) delivered 11 of 11 images with GPU time per step unchanged (713.8 versus 712.7 ms) and 1.26 GiB more host memory.

    Caveats

    • The GGUF route uses fine-tuned Q4_K_M weights, not the original weights; image reverse prompting was out of scope.
    • Per-run numbers come from the archived comparison page (the raw run records are not in the archive).
    17 rows in the speed table →
  13. 13Image DiT Fix VerifiedAfter releasing the CUDA cache after each call, does BF16 stream complete in the production state?2026-10-18

    After the fix (release the CUDA cache after every call and clear frames first on failure), the t2i-pc run that failed in experiment 12 was repeated in the RTX 5080 production state (H3’s vae-5080 and venc-5080 resident): same prompt (a ceramic cup), 1024², 40 steps, seed 42, full VAE decode, with previews off and with a preview every 4 steps.

    Findings

    • Pass: 47.9 s end to end (text encode 12.15 s, DiT 33.04 s, VAE 1.82 s), whole-card NVML peak 11,849 MiB, and the image matches the pre-fix reference pixel for pixel.
    • With a preview every 4 steps, all 11 were published, GPU time per step (p50) rose only 9.0 ms (+1.1%), and the run took 43.0 s end to end (text-encode process already warm).
    • Applied: t2i-pc and i2i-pc now use the BF16 stream DiT with the preview VAE enabled.

    Caveats

    • i2i, four-image batches and 1536² have not been rechecked on the GPU since the fix; the grid texture in preview thumbnails comes from the preview method itself.
    2 rows in the speed table →